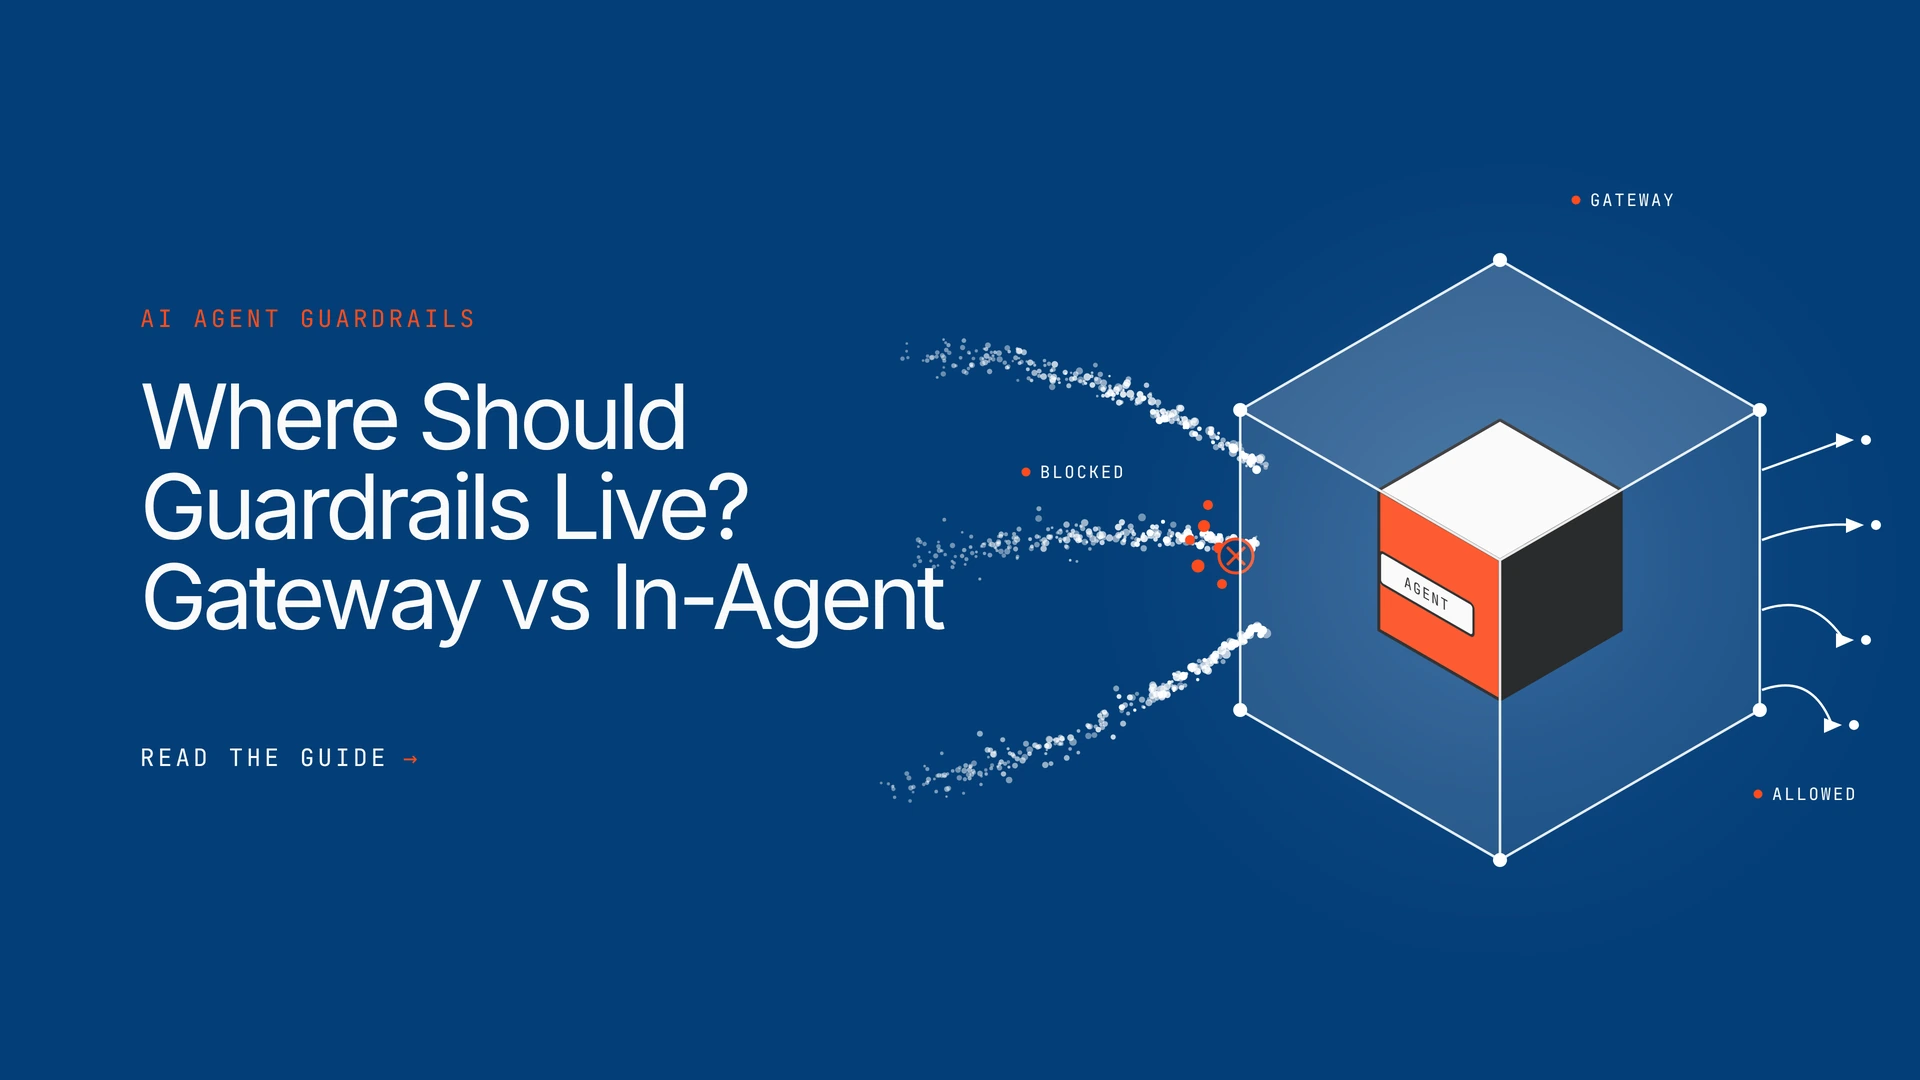
Every team building AI agents reaches the same question: should the rules live inside the agent, or in a gateway that every call passes through? The answer decides who can bypass a rule, what it can see and who keeps it current. This guide explains both options, shows which guardrails belong where, and gives four questions to settle it for your own agents.
TL;DR
- The question: where a guardrail runs decides who can bypass it, what context it sees and who maintains it.
- Gateway: the home for rules that must hold for every agent, such as identity, tool policy, PII and secrets, and budgets.
- In-agent: the home for rules that need task context, such as output schemas, scope in the prompt and loop guards.
- The default: enforce outside the agent, tune inside it, and layer both for high-impact actions.
- The test: ask whether the rule must survive a hijacked agent, needs task state, must apply to every agent, and guards a high-impact action.
What does it mean for a guardrail to live somewhere?
AI guardrails are runtime rules that inspect what goes into and out of a model or agent, then block, modify or redirect anything that breaks a policy. A guardrail is just a check. Where it is called from decides where it lives: inside the agent’s own process, or in the request path between the agent and the models, tools and systems it calls.
The same check can sit in either place. Amazon Bedrock’s ApplyGuardrail API, for example, is described by AWS as decoupled from foundation models, and it can be placed anywhere in an application flow. Placement is a design decision, not a property of the product.

Placement matters more as agents gain reach. Prompt-level safeguards stop being enough once an agent can call APIs, MCP servers and internal systems across multi-step workflows, a point we make in our roundup of AI agent safety tools. The access side of the problem is already visible in the data.

What are in-agent guardrails?
In-agent guardrails are checks that run inside the agent’s own code or prompt. They include scope rules in the system prompt, schema validation of outputs, retry and call limits, and libraries such as NVIDIA NeMo Guardrails, which our safety roundup describes as application-level control living inside the agent’s own process.
They have real strengths:
- Context: they see the task state, the plan and the retrieved passages, so they can judge things a gateway cannot, such as whether an answer matches its source.
- Speed of change: the team that owns the agent can tune them without asking anyone else.
- Precision: task-specific logic, such as validating a structured output or detecting a runaway tool loop, is natural to write next to the agent.
Their weakness is the trust boundary. A check that lives in the agent shares fate with the agent. A hijacked or buggy agent can skip it, rewrite it or never call it, and every framework and repository needs its own copy, so coverage varies from team to team.
What are gateway guardrails?
Gateway guardrails run in the request path, outside the agent, so each model call, tool call and agent-to-agent call is checked before it executes. Our governance control plane explainer likens this layer to an API gateway built for prompts, completions, token cost and content risk.
- Hard to override: the model cannot talk its way past a check it never sees.
- One policy, every agent: a rule change reaches every agent behind the gateway, whatever framework it uses.
- Central ownership and evidence: a platform or governance team owns the rules and holds the audit trail.
- Visibility of actions: the gateway sees tool arguments before the call lands, so it can allow, hold or block a refund before money moves.
The limit is context. A gateway sees what crosses the wire, not the agent’s reasoning or task state. It also helps to separate two jobs. Inbound guardrails filter what reaches the agent, while request-path enforcement governs what the agent does, as we describe in our guide to quarantining a misbehaving agent. A gateway is strongest at the second job.
How do gateway and in-agent guardrails compare?
| Dimension | In-agent | Gateway |
|---|---|---|
| Where it runs | Inside the agent’s process or prompt | In the request path, outside the agent |
| Who can bypass it | A hijacked or buggy agent, which shares its trust boundary | Not the agent: calls are refused before they execute |
| What it sees | Task state, plan and retrieved context | Prompts, responses and tool arguments on the wire |
| Coverage | Only agents that implement it | Every agent behind it, whatever the framework |
| Who owns it | The agent’s team, repository by repository | A platform or governance team, centrally |
| Change speed | Redeploy each agent | One policy change reaches every agent |
| Added latency | No extra hop | One extra hop per call |
| Best for | Schemas, task scope, loop and progress guards | Identity, tool policy, PII and secrets, budgets, approvals |
Which guardrails belong where?
A useful rule of thumb: anything the agent must not be able to relax for itself belongs outside it. Excessive agency, tool misuse and privilege abuse are the risks that rule targets (see the OWASP Top 10 for LLM applications mapped to controls), and the controls for them, such as least privilege for tools and policy enforcement applied outside the agent, sit in the gateway column. For the wider picture, see agent safety in production and the guardrails glossary entry.

Three of the in-agent rows deserve a note. Groundedness checks need the source passages, which the agent already holds. Output schemas are about the shape of the agent’s own result. Loop guards need to know whether the agent is making progress. Each can be backstopped at the gateway, for example with call-rate limits, but the signal lives with the agent. For the groundedness layer in particular, see our guide to preventing hallucinations in production.
How do you decide where a guardrail should live?
Run each guardrail through four questions. The flow below gives the default placement, and the steps after it turn the answers into a rollout.

Step 1: List your guardrails and rank them by blast radiusWrite down every rule you rely on today, including the ones that exist only as a line in a system prompt. Rank each by what a miss would cost: money moved, data exposed, access granted or an embarrassing answer.
Step 2: Ask whether the agent could bypass itIf a hijacked agent could skip, rewrite or never call the check, and a miss is costly, move it outside the agent. Identity, tool permissions and spend limits almost always land here.
Step 3: Ask what context the check needsIf the check needs the task state, the plan or the retrieved passages, keep it in the agent and expose its verdict to the gateway. Forcing context-hungry checks into the gateway leads to crude rules and false positives.
Step 4: Layer the high-impact actions twiceFor actions that move money, change records or grant access, use two independent layers: an in-agent check that the request is well formed, and a gateway rule that holds or blocks it. Add human approval above a threshold you set.
Step 5: Roll out in observe mode, then enforceStart by logging verdicts without blocking, review the false positives, then enforce. Decide per rule what happens when the guardrail itself errors: fail open for low-risk checks that must not cause an outage, fail closed for anything that guards money, data or access.
Step 6: Trace both layers and keep testingRecord which guardrail ran, on which call, with which verdict, so you can tune rules and show evidence to an auditor. Re-run your test scenarios whenever a rule, prompt or tool changes.

A worked example
This example is illustrative, for a hypothetical refund agent.

| Layer | Check | Lives in |
|---|---|---|
| Scope | Only refund requests inside the policy window are handled | In-agent (system prompt) |
| Shape | The refund request has a valid order ID, amount and reason | In-agent (schema check) |
| Identity | The caller is authenticated and allowed to use the refund tool | Gateway |
| Tool limit | Refunds above a set amount are held, not executed | Gateway |
| Approval | A named reviewer approves or rejects the held refund | Gateway plus a person |
| Evidence | The trace records each check, verdict and approver | Gateway and agent |
What are the trade-offs?
Neither placement is free. Plan for four costs:
1. Latency.
A gateway adds a hop on every call. Lyzr’s policy enforcement roundup reports about 11 ms for Opencontroller, a self-reported figure. Treat any vendor number as a starting point and measure in your own environment.
2. False positives.
A blocked hop can fail an entire agent chain. Run new rules in observe mode first, and review what they would have blocked before you enforce.
3. Fail open or fail closed.
When a guardrail errors, you either let the call through or block it. Choose per rule by blast radius, and write the choice down so it is a decision rather than a default.
4. Identity is not content.
Authentication confirms who is calling, not what the call contains. A valid credential can still carry a malicious instruction, so a gateway needs content checks as well as access control.
How do cloud-native and library guardrails fit?
Most teams already own one or more of these. The table shows where each kind lives, based on how the products are described in our roundups of policy enforcement tools and agent safety tools. Those roundups are vendor-authored, so check each product’s own documentation.
| Approach | Examples | Where it lives | Watch for |
|---|---|---|---|
| Library in the agent | NVIDIA NeMo Guardrails, Guardrails AI | Inside the app, or wrapping the LLM call | Each app needs its own update, and it shares the agent’s trust boundary |
| Cloud-native guardrail service | Amazon Bedrock Guardrails, Google Cloud Model Armor | A cloud service, called from the app or a gateway | Policy tends to stop at that cloud’s edge |
| Network or API gateway | Kong AI Gateway, Prisma AIRS | In the request path | Governs traffic rather than the agent itself |
| Sandbox and isolation | NVIDIA OpenShell, containers | Outside the agent process, with a supervisor checking outbound requests | Needs separate infrastructure |
| Agent control plane | Opencontroller by Lyzr | The request path, plus identity, deployment and observability | Needs deployment in your environment |
These are not exclusive. A cloud-native service such as Bedrock Guardrails can be the engine behind a check that is invoked from a gateway. If you are weighing hyperscaler controls against a control plane, see how the Lyzr control plane compares with AgentCore and with Agent 365. Teams running many agents on many platforms will also want to read about AI agent sprawl, because uniform placement is hardest when nobody has counted the agents.
Where does Opencontroller fit?
Opencontroller by Lyzr is the control plane for AI agents. It puts enforcement in the request path, outside the agent, and leaves task-specific checks where they have the context to work. Per the product page, the pieces that matter for this question are:

- Agent Gateway: authenticates, authorizes and rate-limits every caller, whether human, app or agent. Each agent has a public, internal or private access level and a pause control.
- Guardrails: screen inputs, outputs and tool calls for prompt injection, PII, secrets and groundedness, with per-tool limits. In the page’s example, a large refund is held and sent to a reviewer.
- LLM Gateway: virtual keys, team budgets, rate limits, routing, fallback and caching across model providers.
- Identity and observability: a workload identity for each agent through your existing identity provider, and OpenTelemetry traces with cost, quality and owner on every span, exportable to your monitoring tools.
- Deployment: in your VPC, on-prem or air-gapped. For customer-managed setups, the page says no control-plane data, credentials or telemetry go to Lyzr.
| Question | In-agent checks only | Gateway plus in-agent checks |
|---|---|---|
| Can a hijacked agent skip the rule? | Yes, the rule shares its trust boundary | Not for gateway rules, which run before the call executes |
| Does one change reach every agent? | No, each repository updates separately | Yes, for rules held in the gateway |
| Is there evidence for an auditor? | Whatever each team logs | One trace per call, with the verdict and owner |
| Who decides on a high-impact action? | The agent | A named reviewer, after a gateway hold |
Regulated teams get the most from this split, since evidence matters as much as blocking. Our overview of governing agents in regulated industries covers that case, and the Lyzr agent control plane post explains the wider design.
How do you test that guardrails work?
A guardrail you have not attacked is an assumption. Start with red-teaming an AI agent, which turns findings into runtime rules, then build a regression suite so each fix stays fixed. Generating scenarios by hand does not scale, so see our guide to auto generating test scenarios for AI agents for a method that covers the adversarial and edge cases a guardrail must survive.
Test both layers separately. Confirm the gateway blocks a bad tool call even when the agent is instructed to make it, and confirm the in-agent check catches a malformed output even when the gateway would have let it through. If one layer is covering for the other, you only have one layer.
Frequently asked questions
Where should guardrails live in an AI agent system?
Put rules the agent must not be able to relax, such as identity, tool permissions, PII and secrets checks, and spend limits, in a gateway outside the agent. Keep rules that need task context, such as output schemas and loop guards, inside the agent, and layer both for high-impact actions.
What is the difference between gateway guardrails and in-agent guardrails?
In-agent guardrails run inside the agent’s own code or prompt and see its task state, but share its trust boundary. Gateway guardrails run in the request path outside the agent, so every agent behind them gets the same rules, and the agent cannot override them.
What is an AI gateway?
An AI gateway is a layer between applications or agents and the models and tools they call. It authenticates callers, applies policy and guardrails, meters tokens and cost, routes requests and records an audit trail, much as an API gateway does for ordinary APIs.
Do guardrails run before or after the LLM?
Both. Input guardrails screen prompts and tool results before the model sees them, and output guardrails screen responses before they reach a user or a downstream system. Agents also need guardrails on tool calls, which sit between the model’s decision and the action itself.
Can an AI agent bypass its own guardrails?
If the guardrail runs inside the agent, a hijacked or buggy agent can skip, rewrite or never invoke it. A guardrail enforced outside the agent, in the request path, refuses the call before it executes, so the agent has no way to relax it.
Do gateway guardrails add latency?
Yes, a gateway adds one hop per call, and each check adds processing time. Vendor figures are self-reported and vary, for example about 11 ms for Opencontroller in Lyzr’s own roundup, so measure in your environment and run slow checks in parallel or on small, fast models.
Are guardrails enough to secure an AI agent?
No. Guardrails filter and block, but agents also need distinct identities, least-privilege access to tools, budgets, human approval for high-impact actions, monitoring and a way to pause or quarantine an agent. Guardrails are one layer in that stack.
What are the main types of AI guardrails?
Common types are topical guardrails that keep an agent on subject, security guardrails against prompt injection, safety and moderation filters, compliance rules, factual and hallucination checks, and action or tool-use limits that restrict what an agent can do.
Should guardrails fail open or fail closed?
It depends on the blast radius. Fail closed for guardrails that protect money, data or access, so an error blocks the call. Fail open only for low-risk checks where an outage would cost more than a miss, and record the choice for each rule.
Do I need both gateway and in-agent guardrails?
For anything beyond a low-risk prototype, usually yes. The gateway enforces what must always hold and gives you central evidence, while in-agent checks handle the context-dependent rules the gateway cannot see. High-impact actions should pass through both.
How do you test AI guardrails?
Red-team the agent with adversarial scenarios, such as prompt injection and attempts to misuse tools, then keep the cases as a regression suite. Test the gateway and the in-agent checks separately, so a failure in one layer is not hidden by the other.
Put your guardrails where they cannot be skipped
Run a working session with your platform and security teams and leave with a placement map for your agents’ guardrails.
Book A Demo: Click Here
Join our Slack: Click Here
Link to our GitHub: Click Here