Picture a quarterly review where the CFO asks a simple question: how much did our AI agents cost last quarter, and which ones drove that number?
Three teams go away to find out. Support records tokens as prompt_tokens. Sales uses a vendor SDK that logs input_token_count. The internal tools team never logged tokens at all. A week later, the CFO gets three spreadsheets and three numbers that don’t add up.
The teams lacked a shared language for describing what an AI system does. OpenTelemetry GenAI semantic conventions are that language, giving model calls, token usage, tool calls and agent runs one set of names across every framework and backend.
This guide covers what the conventions contain, how to adopt them safely, and what comes after visibility.
Key takeaways
- One vocabulary: LLM calls, agent runs and MCP tool calls all use the gen_ai.* namespace.
- Two core attributes: gen_ai.operation.name and gen_ai.provider.name appear on every GenAI span. The latter replaced gen_ai.system.
- Agents become traces: Operations such as invoke_agent, plan and execute_tool turn an agent run into an ordinary distributed trace.
- Metrics cover cost and behaviour: Standard token, latency and tool-call metrics support cost reporting and loop detection.
- Privacy by default: Prompt and response content is captured only when you opt in.
- Still evolving: The spec is at Development stability, so pin instrumentation versions.
- Visibility isn’t control: Governing agents requires a control plane such as Opencontroller.
What are OpenTelemetry GenAI semantic conventions?
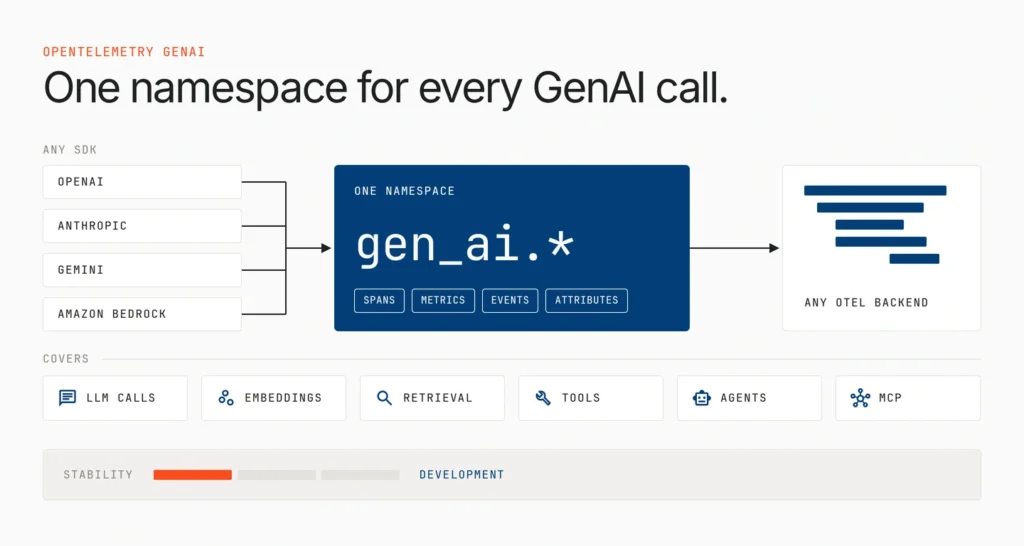
OpenTelemetry GenAI semantic conventions are a vendor-neutral specification that defines how generative AI workloads name their spans, metrics, events and attributes. They cover LLM calls, embeddings, retrieval, tool execution, AI agents and MCP interactions under one gen_ai.* namespace, so any OpenTelemetry-compatible backend reads the data the same way.
OpenTelemetry already uses semantic conventions to make an HTTP request look the same whether it came from Java or Python. The GenAI conventions bring that consistency to AI. A chat call to OpenAI, Anthropic, Gemini or Amazon Bedrock produces the same span structure with the same attribute names, whichever SDK made it.
Where the conventions live today
The GenAI conventions now live in a dedicated repository, open-telemetry/semantic-conventions-genai, together with the MCP conventions. They were moved out of OpenTelemetry’s core repository with semantic conventions v1.42.0 in mid-2026, so the GenAI group can iterate faster than the core project allows. The old attribute registry page now marks every GenAI attribute as moved.
Every gen_ai.* attribute is still at Development stability, the earliest of three levels. Names and span structures can change between releases, so production teams should plan for occasional renames.
Why AI telemetry needed its own standard
AI telemetry needed its own standard because model calls carry a direct cost in tokens and behave non-deterministically, two things traditional conventions never modelled. The same input can produce a different output, tool sequence and bill each time it runs.
Fragmentation made this harder. Each framework invented its own field names, so a model name could appear as modelName, llm_model or something else entirely. Teams that switched frameworks lost their dashboards, and teams running several couldn’t compare them.
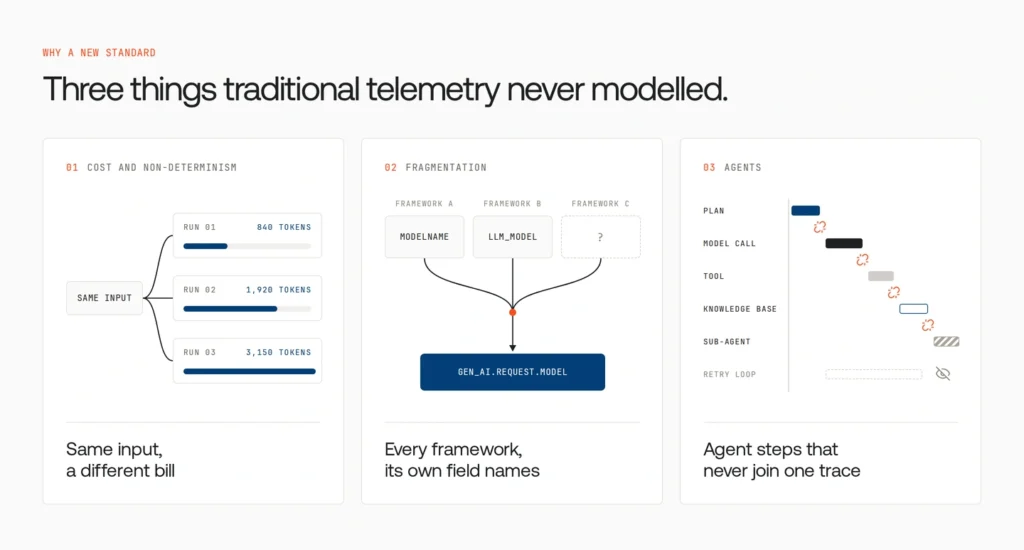
AI agents raised the stakes. An agent plans, calls a model, invokes tools, searches a knowledge base and hands work to sub-agents. When each step uses a different format, the steps can’t be joined into one trace, and retry loops become invisible.
How the conventions describe a single LLM call
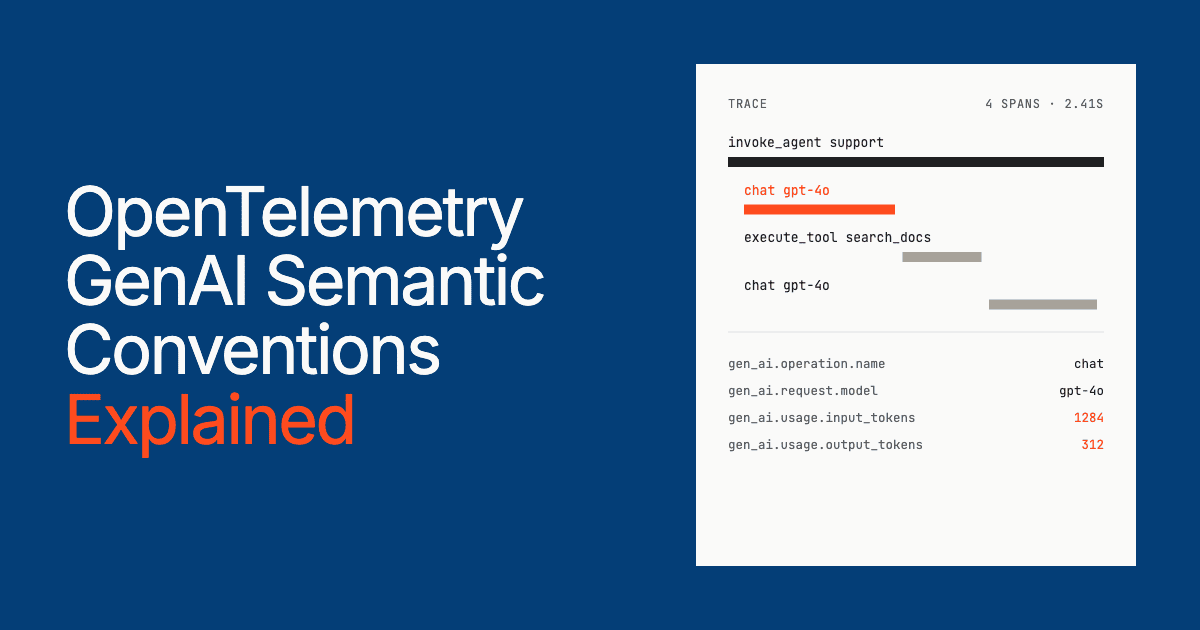
The conventions record each LLM call as a CLIENT span named after the operation and model, so a chat call to GPT-4o produces a span called chat gpt-4o.
| Attribute | What it captures |
| gen_ai.operation.name | Operation type, such as chat, embeddings or execute_tool |
| gen_ai.provider.name | Provider, such as openai, anthropic, aws.bedrock or gcp.vertex_ai |
| gen_ai.request.model / gen_ai.response.model | Model requested and model that actually responded |
| gen_ai.usage.input_tokens / gen_ai.usage.output_tokens | Token counts for cost tracking |
| gen_ai.response.finish_reasons | Why generation stopped, such as stop or length |
The registry also defines gen_ai.usage.cache_read.input_tokens and gen_ai.usage.reasoning.output_tokens, which matter because providers price cached and reasoning tokens differently. Request parameters such as gen_ai.request.temperature link quality or cost changes to configuration changes. Older instrumentation may still use gen_ai.system, which the registry has deprecated in favour of gen_ai.provider.name.
How the conventions describe an AI agent
The conventions describe an AI agent as a tree of spans, one for each step it takes. Agent behaviour is captured through well-known operation names such as create_agent, invoke_agent, plan, invoke_workflow, execute_tool, retrieval and memory operations such as search_memory. Workflows carry gen_ai.workflow.name, which might hold the name of a LangChain chain or a CrewAI crew.
An agent run as a trace
A procurement agent renewing a software licence might produce this trace:
| Span | What happened | Duration |
| invoke_agent procurement-assistant | The full agent run | 18.4s |
| plan procurement-assistant | Breaks the request into steps | 1.2s |
| retrieval vendor-contracts | Finds the current contract | 0.6s |
| chat gpt-4o | Decides a budget check is needed | 1.9s |
| execute_tool budget_api | Calls the finance system; times out | 5.0s |
| execute_tool budget_api | Retries; succeeds | 4.8s |
| invoke_agent approvals-subagent | Hands off for sign-off routing | 3.1s |
| chat gpt-4o | Writes the final response | 1.8s |
The diagnosis takes seconds: more than half the run was spent waiting on a slow finance API.
Step-level spans also make poor answers diagnosable. Retrieval may have pulled the wrong documents from a knowledge base or knowledge graph, the model may have misread good context, or a tool may have failed. Each failure, including hallucinations, needs a different fix.
MCP tool calls
Model Context Protocol servers are now a common way to give agents tools. Because the MCP conventions share the GenAI repository, an MCP tool call produces the same execute_tool span as a direct call.
The metrics that turn traces into answers
Traces explain individual runs, but most operational questions are about patterns over time. The conventions define standard metrics for exactly that.
| Metric | What it measures |
| gen_ai.client.token.usage | Tokens consumed, split by input and output |
| gen_ai.client.operation.duration | Latency of each GenAI call |
| gen_ai.invoke_agent.duration | Total time for an agent run |
| gen_ai.invoke_agent.tool_calls | Tool calls per agent run |
| gen_ai.invoke_agent.inference_calls | Model calls per agent run |
| gen_ai.execute_tool.duration | Execution time per tool |
Standard token metrics answer the CFO’s question: spend can be grouped by agent, team or model and refreshed continuously.
Agent-level metrics catch what latency misses. Rising tool calls per run often signal a retry loop before the cost spike appears. Rising model calls without matching tool calls suggest an agent re-planning instead of acting.
Prompts, responses and PII: how content capture works
Content capture is opt-in, so prompts and responses stay out of your observability backend unless you enable them. Security teams usually raise this question first.
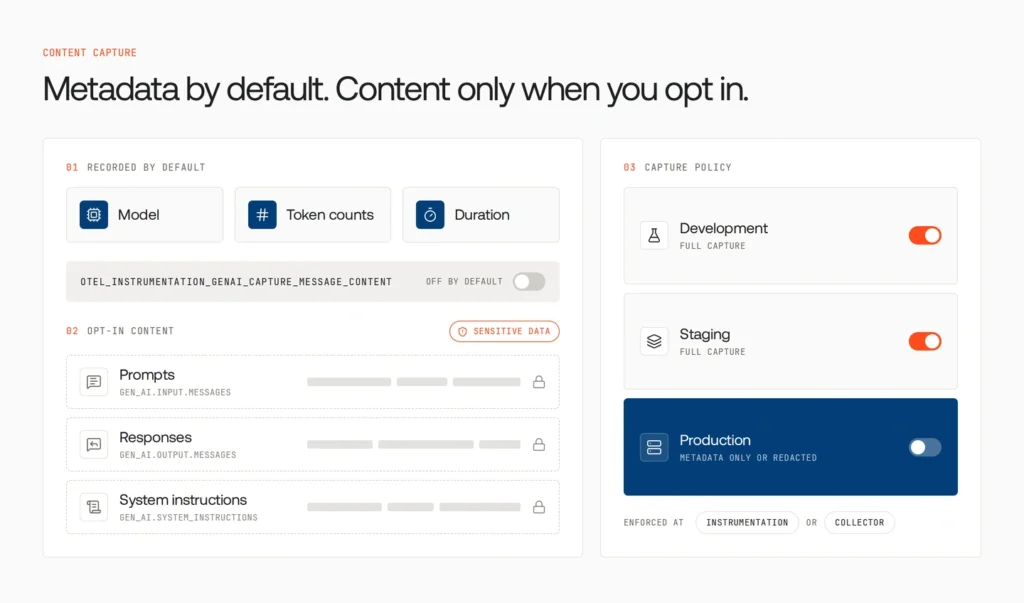
By default, instrumentation records only metadata such as model, token counts and durations (OpenTelemetry blog). Prompts, responses and system instructions are recorded through gen_ai.input.messages, gen_ai.output.messages and gen_ai.system_instructions only when enabled, and the registry flags these attributes as likely to contain sensitive data.
Libraries commonly use a setting such as OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT, but accepted values vary, so check your instrumentation’s documentation. A practical policy is full capture in development and staging, and metadata only (or redacted content) in production, enforced at the instrumentation or Collector layer.
Adopting a standard that’s still in development
Teams can adopt the GenAI conventions in production today, provided they treat attribute names as subject to change. The OpenTelemetry blog shows VS Code Copilot, OpenAI Codex and Claude Code exporting OpenTelemetry telemetry, viewed in the Aspire Dashboard. The OpenTelemetry Demo includes a LangGraph agent with MCP tools. Datadog ingests conventions from v1.37 onward, and MLflow can export traces in the gen_ai.* format.

Development status still calls for discipline:
- Pin instrumentation versions and review changelogs before upgrading.
- Opt in deliberately. Libraries that emitted older conventions support OTEL_SEMCONV_STABILITY_OPT_IN=gen_ai_latest_experimental. Test the switch in staging first.
- Normalize at the Collector. A transform processor can map legacy attribute names onto gen_ai.* equivalents.
- Centralize attribute names in one shared module so a rename is a one-line change.
The question telemetry can’t answer
With one accurate number for AI spend, the CFO’s next questions are harder.
Why was the procurement agent allowed to retry the finance API so often? Who approved the support agent version that doubled its token use? Which agents are running in SaaS tools that IT doesn’t know about? And if an agent overspends at 2 a.m., what actually stops it?
Telemetry can’t answer these, because they’re about control, not visibility. A dashboard can show an agent burning through its budget, but it can’t refuse the agent’s next call. A policy document can’t enforce itself.
The gap widens with every new agent across clouds, SaaS products, Kubernetes clusters and laptops. GenAI semantic conventions solve visibility. The other half needs a control plane that knows which agents exist, decides what they can access and spend, and enforces those rules where agents run.
Not sure how many agents are running across your stack? Take the AI Agent Sprawl Audit to map your agent estate and find the gaps telemetry alone can’t close.
Opencontroller: turning GenAI telemetry into agent control
Opencontroller from Lyzr is an open control plane for an organization’s entire agent estate. Like OpenTelemetry, it works across any cloud, framework, model and runtime instead of tying you to one vendor.
| The challenge | How Opencontroller addresses it |
| No complete inventory of agents | Find: discovers agents, models, tools, data and workflows across clouds, SaaS, Kubernetes and devices |
| Agents reach production unchecked | Ship: evaluates and governs every agent before production, with ordered promotion and separation of duties |
| Monitoring is fragmented | Run: monitors agents, apps, APIs and infrastructure in real time from one control plane |
| Alerts fire but nothing stops the agent | In-path enforcement: refuses the call in the request path when policy says no |
| Signals go unused | Improve: turns usage, performance, cost and security signals into insights |
The quarterly review, with a control plane
With Opencontroller in place, every agent appears in one inventory. Each has an owner, an approved version and defined limits. When the procurement agent began looping, its calls were refused in the request path before the problem reached the budget report. Because versions are immutable, rolling back the expensive support agent release is a pointer move. Every decision and blocked call stays traceable for the audit trail.
Built for the agents you already run
Opencontroller governs existing containerized agents without rewrites, whether hand-written or built in Lyzr Studio. It runs inside your own infrastructure with no traffic to the vendor, which suits organizations pursuing sovereign AI, and it enforces policy on agents in other vendors’ clouds. Lyzr says setup takes less than a week.
Try the live Opencontroller demo
Frequently asked questions
OpenTelemetry GenAI semantic conventions are a vendor-neutral standard for naming the spans, metrics, events and attributes that generative AI workloads produce. They cover LLM calls, embeddings, retrieval, tool execution, AI agents and MCP interactions under the gen_ai.* namespace, so any compatible backend can read them.
The GenAI semantic conventions are not yet stable. Every gen_ai.* attribute sits at Development status, so names and span structures can still change between releases. The conventions now live in a dedicated repository, which lets the working group iterate faster than OpenTelemetry’s core specification.
Prompt and response content is not captured by default. Instrumentation records metadata such as model, provider, token counts and duration. Content capture must be switched on explicitly, and the setting varies by library, so most teams enable it only in development or staging environments.
AI agents and MCP are both covered. Operations such as invoke_agent, plan, execute_tool and retrieval model each agent step as a span, while metrics track agent duration, tool calls and model calls. MCP tool calls use the same execute_tool span as direct tool calls.
Observability alone is not enough to govern AI agents. Telemetry shows what agents are doing, but it cannot stop an agent that is looping, overspending or reaching data it shouldn’t. A control plane such as Opencontroller enforces access, spend and deployment policies in the request path.
Conclusion
OpenTelemetry GenAI semantic conventions give AI systems the shared language they were missing. Adopt them carefully: pin instrumentation, normalize at the Collector and keep content capture off in production. Once you can see what every agent is doing, make sure each one only does what it’s allowed to. That’s the role of Opencontroller.
Book A Demo: Click Here
Join our Slack: Click Here
Link to our GitHub: Click Here
Got a use case in mind?
8 weeks from use case to agents running in production.
Platform, people and FDEs, all in. Bring your environment. We'll co-build and stay until it's live.
Talk to UsFree resource
101 AI Agents Use Cases
100+ production-ready AI agent use cases across Marketing, Sales, HR, Banking, Insurance, Operations and a lot more
Download now